Pearson or Spearman Correlation? Choose and Report the Right Analysis
A practical decision path for researchers using SPSS: inspect the variables and plot, choose the coefficient, then report what the output does—and does not—show.
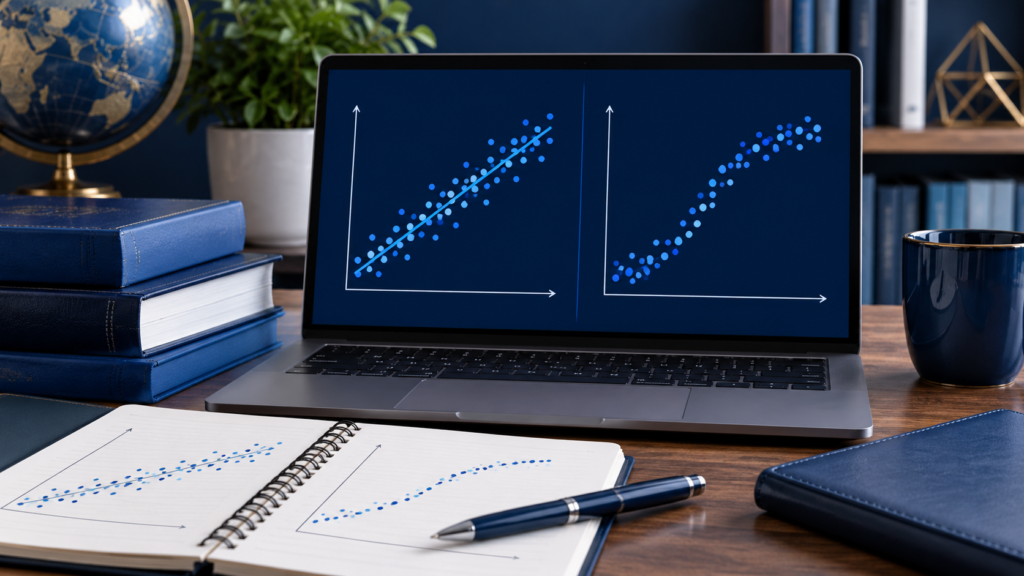
Short answer: Pearson describes linear association between two quantitative variables; Spearman describes monotonic association using ranks and can suit ordinal variables or a relationship that is monotonic but not well represented as linear. Neither proves that one variable causes the other. Decide from your research question, measurement scale, scatterplot and data quality, not from a single normality-test p-value.
IBM’s SPSS correlation documentation describes Pearson output and case counts. The UCLA OARC annotated output explains the coefficient, significance and missing-case choices. These sources document the software; your supervisor, protocol or discipline’s reporting standard governs the final analysis.
1. Make the choice from the variables and relationship
Variable type
Pearson: Both are meaningful quantitative measurements.
Spearman: One or both are ordered categories, or ranks are the intended measurement.
Relationship pattern
Pearson: The scatterplot supports an approximately linear relationship.
Spearman: The relationship is monotonic but curved, or rank order is the substantive question.
Outliers and distribution
Pearson: Influential points and inference assumptions have been assessed.
Spearman: Ranks better represent the question, after inspecting ties and unusual points.
What the answer means
Pearson: Direction and strength of linear association.
Spearman: Direction and strength of monotonic rank association.
Do not treat Spearman as an automatic repair for poor data. A U-shaped relationship can have a meaningful pattern even when both simple coefficients are near zero. A single unusual observation can alter an estimate. Plot the paired values first, check coding and missingness, and discuss the study design with a statistician when inference matters. If your research question asks for prediction or adjustment for other variables, simple bivariate correlation may be insufficient.
2. Run SPSS and check what was analysed
- Define the pair: write the two variable names, units, measurement scales and expected direction before opening the dialog.
- Inspect the data: review a scatterplot, missing values, implausible codes and influential observations. Check whether the same participants contribute to both variables.
- Select the procedure: in SPSS, use Analyze → Correlate → Bivariate and choose Pearson or Spearman according to your decision. IBM’s bivariate-correlations guidance documents both options and explains the procedure and missing-case options.
- Read the whole table: record the coefficient, two-sided significance value if used, and the valid N. UCLA notes that pairwise and listwise missing-data choices can change which cases contribute to a matrix.
- Check sensitivity: if the choice is uncertain, examine whether the answer changes materially under a justified alternative. Explain the chosen analysis rather than selecting whichever p-value looks favourable.
Large sample size can make a small association statistically detectable; a substantial coefficient can remain imprecise in a small sample. A p-value answers a limited statistical question and does not measure practical importance. Avoid generic labels such as “strong” without explaining the field, scale and context.
3. Interpret a worked result without inventing causation
Fictional teaching example—not a real study or computed SPSS output: an MBA student asks whether monthly training hours and customer-service assessment scores move together. Both are quantitative. The scatterplot appears roughly upward and linear, with no obvious extreme point. The student preselects Pearson. Imagine the output reports r = .42, two-sided p ≈ .019 and valid N = 31.
A defensible interpretation is: “In this illustrative sample, training hours and assessment scores had a positive linear association (r = .42, N = 31, two-sided p ≈ .019).” It does not establish that training caused the scores. Prior skill, team support or selection into training could affect both. The researcher should disclose the observational design, plot the data and discuss uncertainty and practical size.
Now imagine the second variable is a five-level ordered supervisor rating rather than a quantitative test score. A rank-based Spearman question could be more appropriate. The researcher would report Spearman’s rho, not relabel a Pearson result. Do not swap methods after seeing the result merely to obtain significance.
4. Write a reproducible results paragraph
Include the scatterplot or a clear table when useful, document exclusions and missingness, and keep the interpretation consistent with the preregistered or approved plan. If multiple correlations are tested, address the multiplicity and exploratory status with the research supervisor rather than presenting the smallest p-value alone.
Frequently asked questions
Is Spearman always required when a normality test fails?
No. The decision also depends on measurement, relationship shape, sample design, outliers and the inference you intend. Inspect the actual paired observations and justify the choice.
Can correlation establish that a training programme works?
No. Correlation alone cannot separate training effects from other explanations. A causal question needs a suitable design and analysis.
Why does SPSS show a different N for different pairs?
Missing values and the chosen exclusion rule can change the cases used. Review the output and report the valid paired sample for the specific result.
Review the method and interpretation
Labeeb can help researchers check the method, SPSS output and wording through statistical analysis support or academic support. The analysis and academic claims remain the researcher’s responsibility; we do not invent data or guarantee publication.
 Conceptual vs Theoretical Framework: Build a Model Your Methods Can Use